One Bad Host
In a hall in Ohio, one machine can have a bad day and stop the work of tens of thousands of others. That is not a metaphor. It is how Meta describes Prometheus, the supercluster that trained Muse Wonder, and the reason its AI story is now an operations story.
Key · companies amber, places red
Prometheus sits in New Albany, Ohio. Two years ago it served web traffic. Meta rebuilt it for frontier training. The first phase is complete. At full scale it will hold roughly one million GPUs across several buildings, wired as one machine.
Meta published the engineering on the 19th of October. At its worst, it recorded nearly 1,000 interruptions per 8,000 GPUs daily. Meta says that is down 99 per cent. NVIDIA repeated the figure within the hour and credited co-engineering.
The unit of failure explains the obsession. Seventy-two GPUs now sit in one NVLink domain and behave as a single accelerator. A fault in that domain can stall the job. A 32,768-GPU run needs 523 racks and 37,656 GPUs, because Meta keeps eight spares in every rack and roughly 2 per cent more racks in reserve. One switch can take out 72 GPUs.
Even one underperforming host can slow an entire training run.
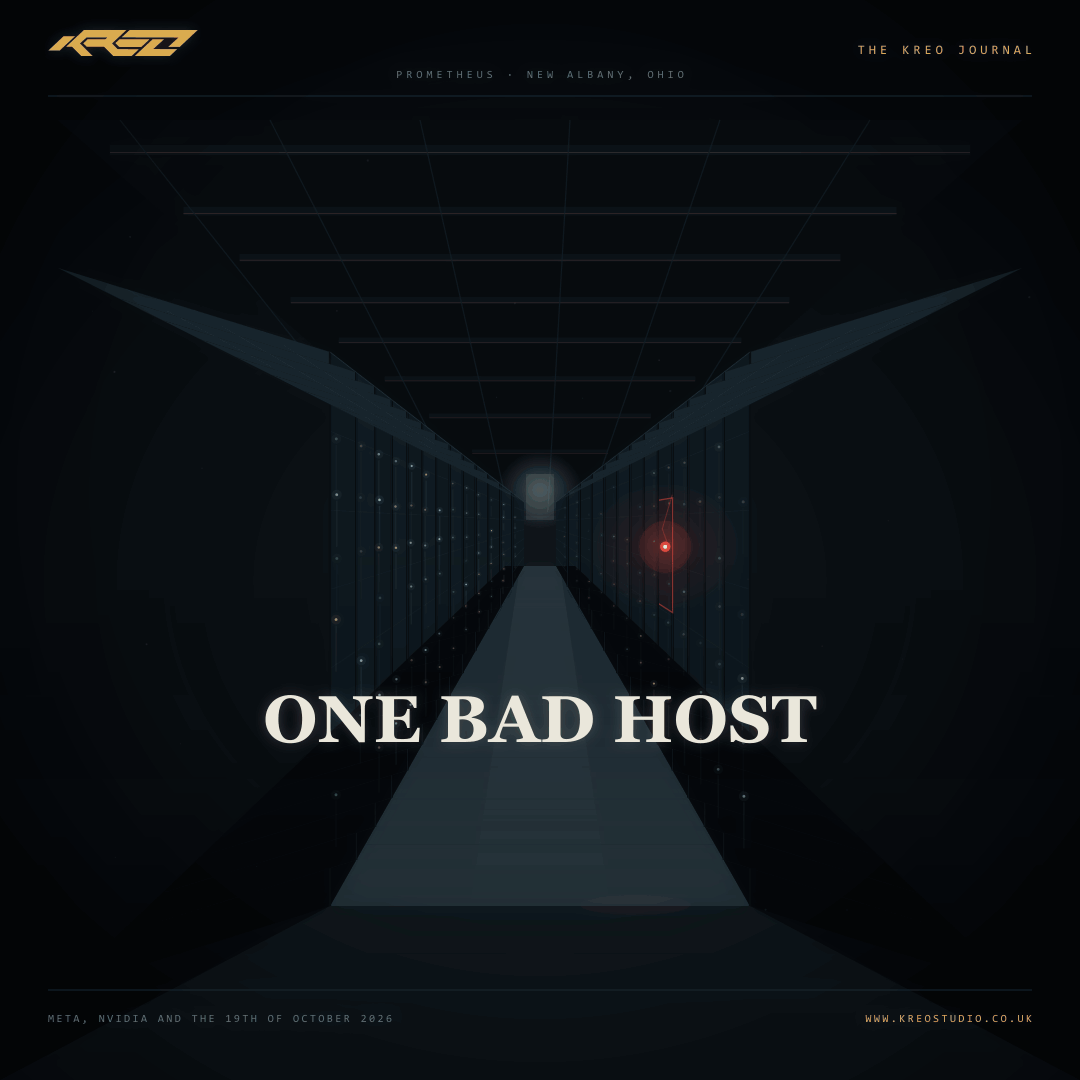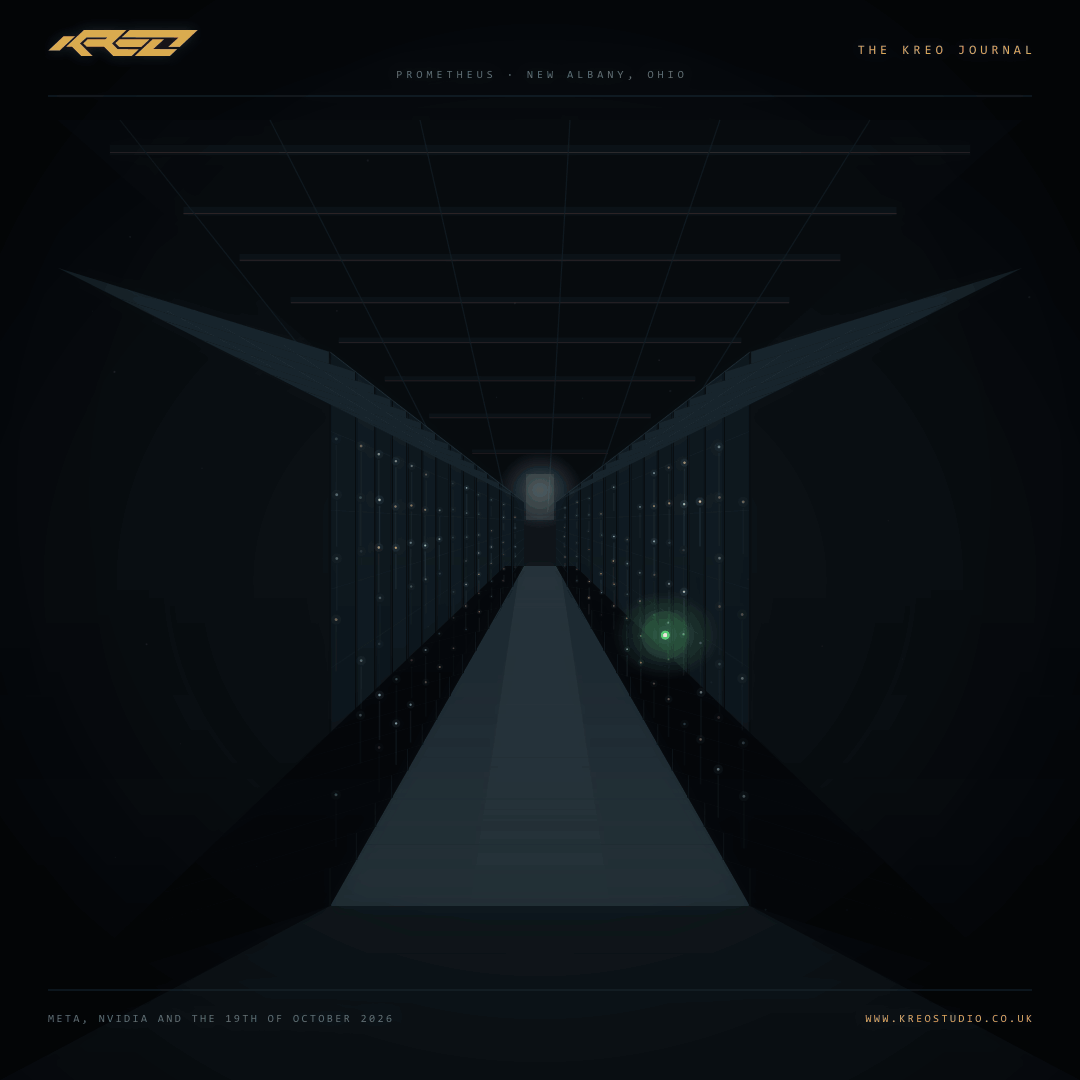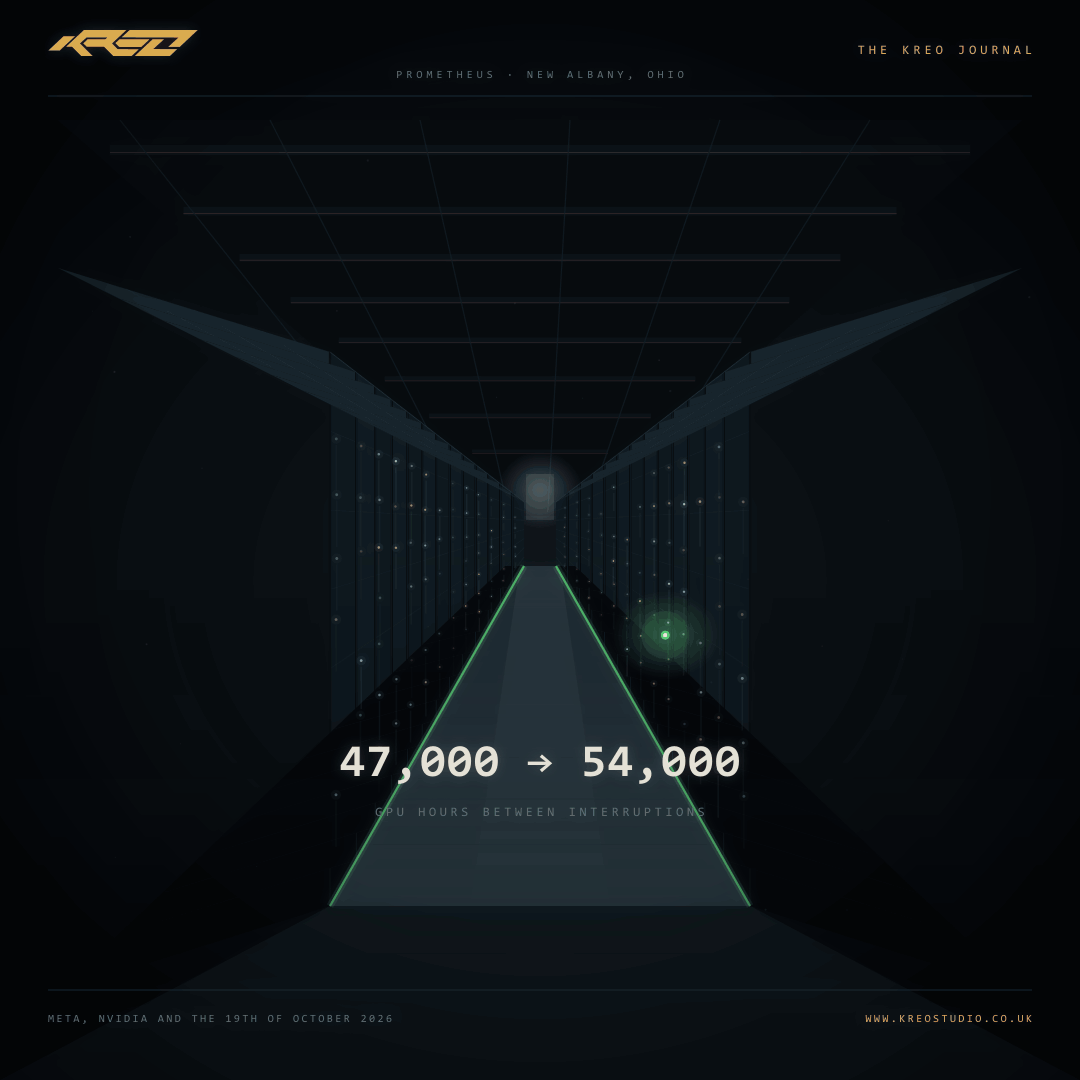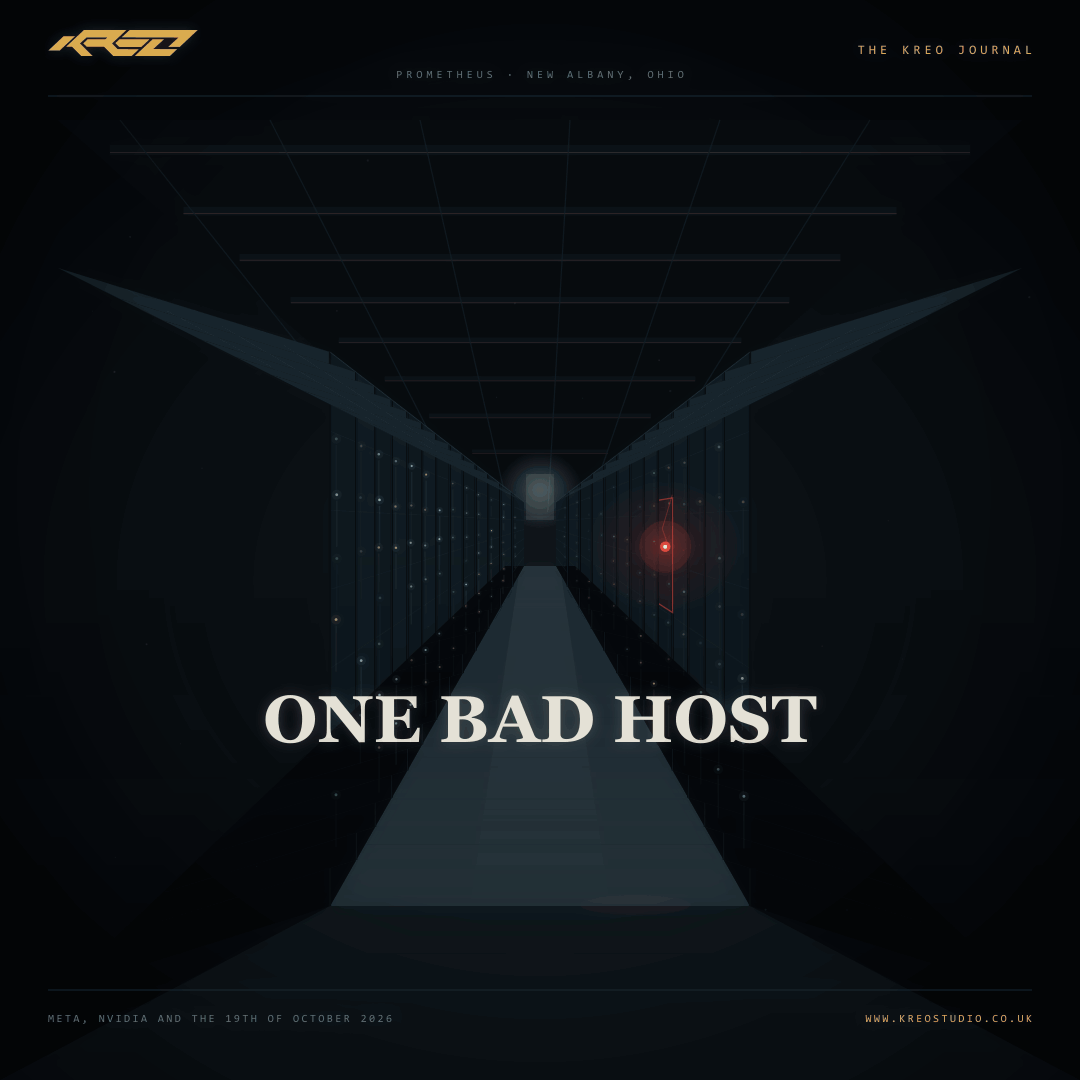
The result is not perfection. Meta reports more than 85 per cent goodput for pre-training and more than 90 per cent for reinforcement learning. Mean time between interruptions rose from about 47,000 GPU hours to more than 54,000. The stated target is 100,000. I measured the cadence: across 8,000 GPUs, that is an interruption every 6.75 hours now, and 12.5 at the target.
That is the unglamorous part of the AI race. The model gets the headline. The scheduler, firmware, spare tray and memory scrub decide whether it exists on time. Meta also manages power swings of 30 to 40 per cent with a system it calls Dynamo Dimmer.
The turn is bigger than one cluster. For twenty years Meta’s advantage was the social graph: 3.6 billion people and the connections between them. Prometheus is a different graph. Its nodes are accelerators, its edges are fibre, and its product is a model that can work for hours without falling over.
The money is blunt. Meta reports $31.08 billion spent on property and equipment and guidance of $130 billion to $145 billion for 2026. Meta reports free cash flow of $784 million, long-term debt of $83.66 billion, and revenue of $60.8 billion, up 28 per cent.
The second business is the point. Muse Wonder, launched on the 12th of October, was trained at Prometheus. Meta positions it for personal and professional agents: memory, sustained work, coding. That is Anthropic’s ground. Anthropic told investors its third-quarter revenue reached $16.8 billion, up 45 per cent. Meta spent nearly twice that on computing in a single quarter.
NVIDIA is not a neutral supplier in this. It supplied the GB200 and GB300 racks, will supply Vera Rubin, and has engineers embedded with Meta’s teams, sharing telemetry and triaging faults. NVIDIA gets the public proof that its racks can be run at a million-GPU scale. Meta’s account credits NVIDIA with firmware, signal diagnostics and memory handling. Neither company can claim the reduction alone.
The catch is the baseline. The 99 per cent reduction that Meta reports sounds close to solved. It is a reduction from a cluster that failed constantly. Ten to fifteen per cent of the most expensive compute on earth is still lost. The million GPUs are a plan, not a photograph. The figures are the company’s own.
The question for everyone else is not whether Meta catches Anthropic. It is whether reliability is becoming the product. Agents that work for hours are only useful if the machine behind them does not flinch. That standard will reach every buyer running a model on their own hardware.
None of this makes Anthropic’s position safe, or Meta’s inevitable. Anthropic is selling judgement. Meta is buying capacity, and learning to operate it. The first is a product. The second is a moat that takes years, substations and a great many spare trays to copy.
It has learned to keep a million machines in conversation. The social graph was built on who you know. The AI graph is built on what stays up.
Readout: what is confirmed, and what is not
- Confirmed, from Meta’s engineering post of the 19th of October 2026: Prometheus is in New Albany, Ohio; the first phase is complete and trained Muse Wonder; it is planned to reach about one million GPUs; interruptions fell 99 per cent from nearly 1,000 per 8,000 GPUs per day; goodput is above 85 per cent for pre-training and 90 per cent for reinforcement learning; MTBI is 47,000 to 54,000 GPU hours, against a target of 100,000.
- Confirmed, from Meta’s second-quarter 2026 results: capital expenditure including finance leases was $31.08 billion; 2026 guidance is $130 billion to $145 billion; free cash flow was $784 million; long-term debt was $83.66 billion; revenue was $60.8 billion, up 28 per cent; 3.60 billion daily users.
- Reported, from Reuters on the 14th of October 2026, citing the Financial Times and an investor meeting: Anthropic’s third-quarter revenue was $16.8 billion, up about 45 per cent. It has not published audited quarterly accounts.
- Calculated by me: 54,000 GPU hours over 8,000 GPUs is 6.75 hours between interruptions; 100,000 over 8,000 is 12.5 hours; Meta’s quarterly capex is about 1.85 times Anthropic’s reported quarterly revenue.
- Company figures, not audited: the 99 per cent, goodput and MTBI numbers. Not confirmed: one million GPUs on the stated timeline, or that the gains hold at that scale. An independent interruption measurement would change my mind.
Sources & references
- Meta Engineering, Inside Prometheus: Meta’s Journey to a Gigawatt-Scale Supercluster, the 19th of October 2026.
- Meta AI, Muse Wonder: A Frontier Model For Personal & Professional AI Agents, the 12th of October 2026.
- Meta Investor Relations, Meta Reports Second Quarter 2026 Results, the 29th of July 2026.
- NVIDIA AI Infrastructure, post on X about Prometheus and Muse, the 19th of October 2026.
- Reuters, Anthropic revenue jumps to $16.8 billion in third quarter, FT reports, the 14th of October 2026.
Reader signal
Was this useful?
Work with KREO Studio
AI engineering, data science and design architecture, from Plymouth to the wider UK.
Next Article
It Haggled Beautifully for the Wrong Book
From the KREO Journal · kreostudio.co.uk/blog/one-bad-host · published the 19th of October 2026. Corrections are dated, never silent.